BVB: Benchmarking Agentic Video Understanding
via Programmatic Reconstruction in Blender
If an agent truly understands a video, it can reconstruct it programmatically.
Dual VQA 62.5Latent Similarity 90.0
Both previews are time-scaled to 30 seconds, so one point on the timeline shows the same relative moment in each video. Scores are for this scene and model.
Overview
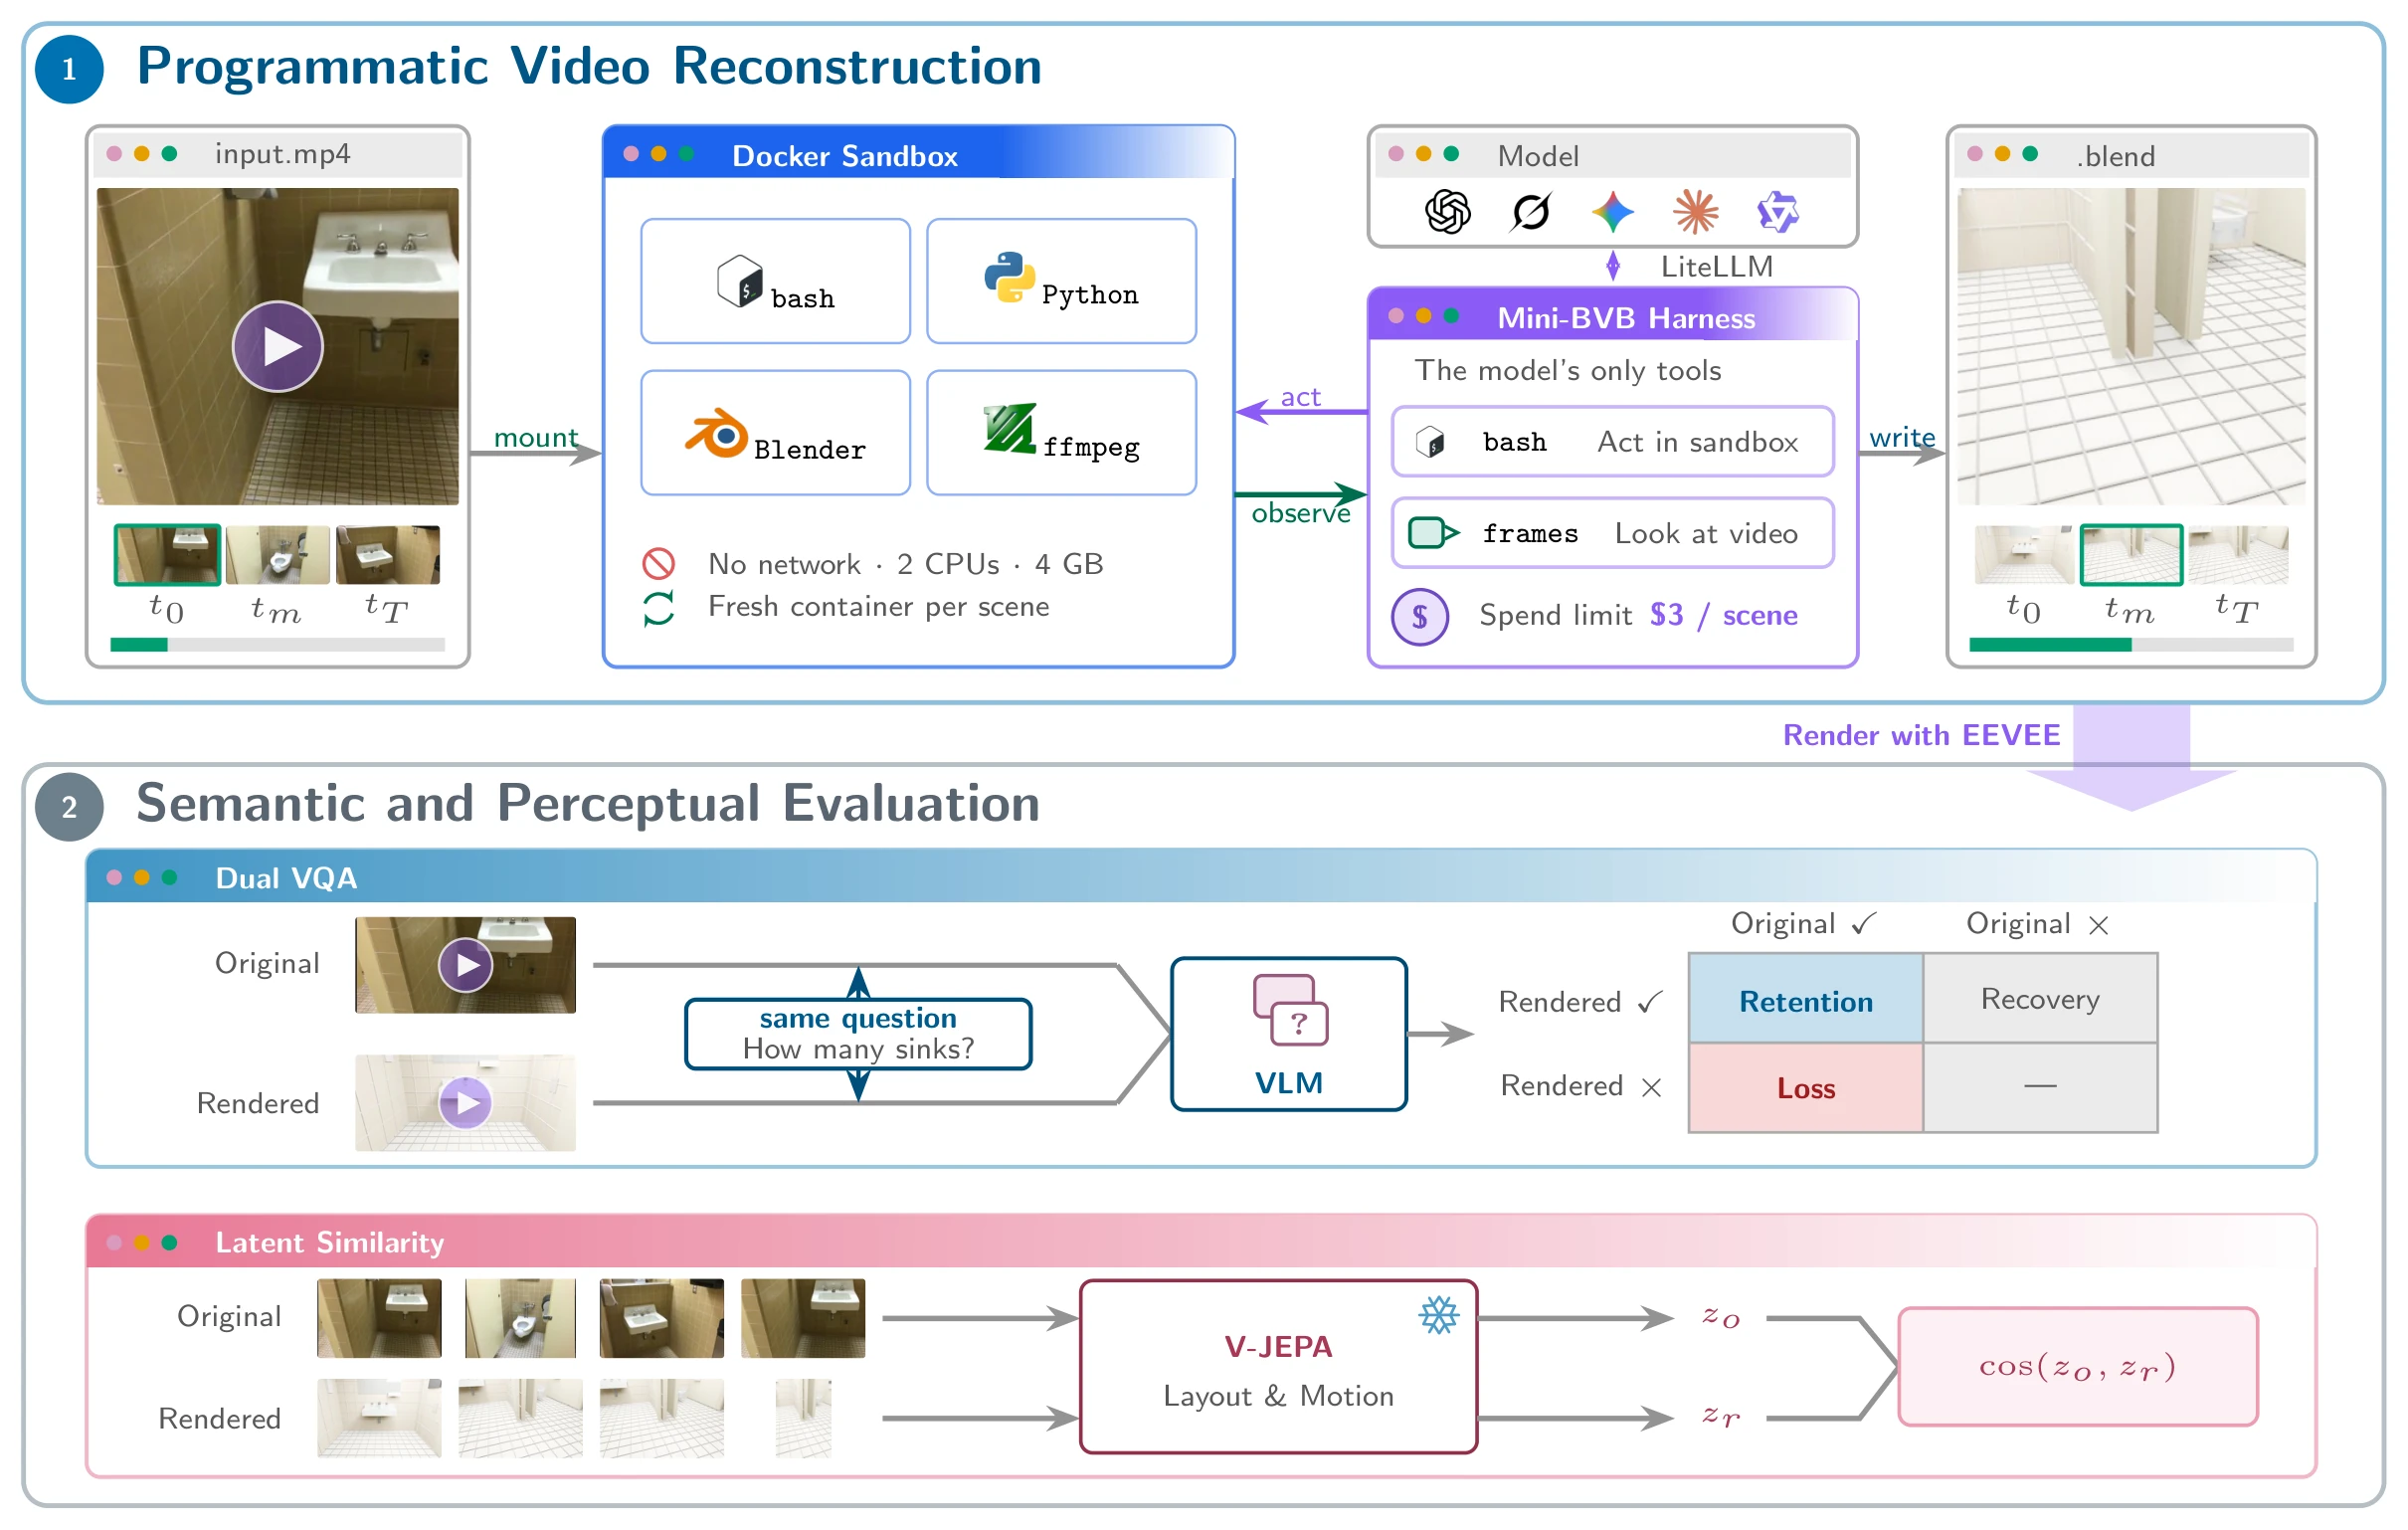
Video understanding benchmarks usually ask a model questions about a video and grade the answers. BVB tests understanding through reconstruction instead. An agent watches a real indoor video and writes Python code for Blender that reconstructs it as an animated 3D scene, with a camera that follows the path of the original video. A faithful reconstruction requires the agent to understand the layout of the room, the objects in it, and how the view changes over time.
Every agent works under the same conditions. It sees only the video frames, runs code in the same sandbox through the Mini-BVB harness, and has the same cost limit for each scene. The saved scene is rendered and compared with the source video on two axes. Dual VQA measures whether the reconstruction keeps the spatiotemporal facts that a VLM judge can answer from the source video. Latent Similarity measures how closely the reconstruction matches the source in layout and motion. Overall combines the two and is high only when both are high.
The leaderboard covers 67 configurations from 13 providers on all 288 test videos. It is updated as new models are evaluated.
Leaderboard
Each configuration is one model at one reasoning effort setting. Every run uses the Mini-BVB harness with no fine-tuning. Scores are on a 0 to 100 scale.
Overall score of the configuration with the highest Overall for each model on all 288 test scenes. Higher is better.
| Rank | Model and reasoning effort | ||||
|---|---|---|---|---|---|
| 1 | GPT-6 Astra xhigh | 76.33 | 64.7 | 88.9 | $1.718 |
| 2 | GPT-6.1 Sol xhigh | 75.41 | 62.4 | 89.7 | $0.500 |
| 3 | GPT-6.1 Terra xhigh | 75.16 | 63.1 | 88.2 | $0.296 |
| 4 | GPT-6 Astra high | 73.95 | 60.6 | 88.6 | $1.258 |
| 5 | GPT-6 Sol xhigh | 73.41 | 62.2 | 85.6 | $0.397 |
| 6 | Gemini 4 Argon high | 72.69 | 61.2 | 85.2 | $0.313 |
| 7 | Claude Opus 5.5 xhigh | 72.39 | 61.3 | 84.5 | $1.950 |
| 8 | Claude Sonnet 5.5 xhigh | 72.27 | 61.5 | 83.9 | $1.183 |
| 9 | GPT-5.6 Sol xhigh | 71.78 | 59.4 | 85.4 | $0.778 |
| 10 | Grok-4.6 xhigh | 70.86 | 58.7 | 84.2 | $1.682 |
| 11 | GPT-6 Luna xhigh | 70.32 | 58.6 | 83.1 | $0.011 |
| 12 | Grok-4.7 xhigh | 70.07 | 58.8 | 82.4 | $1.482 |
| 13 | DeepSeek V4.1 Flash 1017 max open-weight | 70.02 | 58.7 | 82.4 | $0.037 |
| 14 | Claude Opus 5 high | 69.53 | 58.6 | 81.4 | $2.157 |
| 15 | Qwen3.8-Max high | 69.39 | 58.4 | 81.3 | $0.599 |
| 16 | GPT-5.6 Sol high | 69.21 | 55.9 | 83.9 | $0.419 |
| 17 | Glimpse max | 68.86 | 58.0 | 80.7 | $0.365 |
| 18 | GPT-5.6 Terra high | 68.76 | 56.3 | 82.4 | $0.122 |
| 19 | GPT-5.5 high | 68.55 | 56.5 | 81.8 | $0.956 |
| 20 | Claude Haiku 5.5 xhigh | 68.37 | 57.5 | 80.1 | $0.027 |
| 21 | GPT-5.6 Terra xhigh | 68.37 | 55.2 | 82.9 | $0.235 |
| 22 | Claude Opus 5.5 high | 68.15 | 58.6 | 78.5 | $0.493 |
| 23 | GPT-5.6 Sol none | 68.08 | 56.6 | 80.6 | $0.212 |
| 24 | GLM-5.3-Flash xhigh open-weight | 67.91 | 58.0 | 78.7 | $0.024 |
| 25 | GPT-5.6 Sol medium | 67.90 | 55.5 | 81.6 | $0.271 |
| 26 | Muse Wonder xhigh | 67.42 | 57.7 | 77.9 | $1.326 |
| 27 | Muse Spark 1.3 xhigh | 67.13 | 55.6 | 79.7 | $0.229 |
| 28 | DeepSeek V4.1 Flash max open-weight | 66.82 | 57.8 | 76.4 | $0.018 |
| 29 | GPT-5.5 medium | 66.70 | 54.2 | 80.5 | $0.562 |
| 30 | GPT-5.6 Luna high | 66.69 | 53.7 | 81.1 | $0.080 |
| 31 | Grok-4.5 high | 66.42 | 54.9 | 79.0 | $0.300 |
| 32 | GPT-5.6 Sol low | 66.28 | 54.4 | 79.3 | $0.200 |
| 33 | GPT-5.6 Terra medium | 66.27 | 55.0 | 78.5 | $0.149 |
| 34 | Gemini 3.8 Flash high | 65.92 | 55.4 | 77.4 | $0.628 |
| 35 | GPT-5.5 low | 65.63 | 54.7 | 77.5 | $0.320 |
| 36 | GPT-5.6 Luna medium | 65.59 | 53.6 | 78.8 | $0.047 |
| 37 | Claude Sonnet 4.6 none | 65.29 | 56.0 | 75.3 | $0.432 |
| 38 | GPT-5.2 high | 65.18 | 55.4 | 75.8 | $0.578 |
| 39 | GPT-5.6 Terra low | 64.67 | 53.6 | 76.8 | $0.146 |
| 40 | Claude Sonnet 5 none | 64.64 | 55.4 | 74.6 | $0.644 |
| 41 | Gemini 3.1 Pro high | 64.62 | 55.5 | 74.5 | $0.667 |
| 42 | Claude Sonnet 5 high | 64.16 | 54.7 | 74.4 | $0.421 |
| 43 | Claude Opus 4.6 none | 64.09 | 54.5 | 74.5 | $0.672 |
| 44 | Claude Sonnet 4.6 high | 64.05 | 54.0 | 74.9 | $0.747 |
| 45 | Claude Opus 4.7 none | 63.57 | 55.1 | 72.6 | $0.369 |
| 46 | Muse Spark 1.2 xhigh | 63.40 | 52.4 | 75.4 | $0.235 |
| 47 | GPT-5.6 Luna low | 63.24 | 52.0 | 75.6 | $0.027 |
| 48 | Claude Opus 4.8 none | 62.55 | 53.6 | 72.2 | $0.325 |
| 49 | Claude Opus 4.8 high | 62.21 | 53.2 | 71.9 | $0.460 |
| 50 | Gemini 3 Flash high | 62.14 | 55.7 | 69.0 | $0.083 |
| 51 | Claude Opus 4.7 high | 62.08 | 53.7 | 71.1 | $0.351 |
| 52 | GPT-5.2 none | 61.87 | 53.9 | 70.4 | $0.120 |
| 53 | GPT-5.4 none | 60.53 | 53.5 | 68.0 | $0.203 |
| 54 | GPT-5.5 none | 60.34 | 48.4 | 73.6 | $0.163 |
| 55 | GPT-5.4 Mini none | 60.16 | 53.2 | 67.5 | $0.034 |
| 56 | Kimi-K2.5 none open-weight | 59.64 | 50.8 | 69.2 | $0.150 |
| 57 | GLM-5V-Turbo none | 59.00 | 51.5 | 67.0 | $0.276 |
| 58 | MiniMax-M3 none open-weight | 58.18 | 50.9 | 65.9 | $0.058 |
| 59 | Qwen3.5-122B none open-weight | 56.85 | 50.3 | 63.8 | $0.225 |
| 60 | Grok-4.3 high | 56.58 | 49.3 | 64.3 | $0.101 |
| 61 | Qwen3.5-397B none open-weight | 56.32 | 49.5 | 63.5 | $0.179 |
| 62 | Seed-2.0-Mini none | 55.87 | 50.2 | 61.9 | $0.028 |
| 63 | Qwen3.6-Plus none | 53.94 | 46.2 | 62.2 | $0.170 |
| 64 | Grok-4.3 none | 52.37 | 47.8 | 57.2 | $0.047 |
| 65 | Nemotron 3.5 Super VL max open-weight | 52.11 | 47.1 | 57.4 | $0.122 |
| 66 | Seed-2.0-Lite none | 51.90 | 45.8 | 58.4 | $0.039 |
| 67 | Qwen3.5-27B none open-weight | 50.74 | 44.5 | 57.3 | $0.073 |




No configurations match these filters.
Scores cover all 288 test scenes. Latent Similarity is the mean over scenes, and Dual VQA pools the 1,962 questions GPT-5.4 Mini answers correctly on the source videos. A scene with no renderable file scores zero on both axes. Rank follows the sorted column over all configurations and does not change when you filter the table. Ties in displayed scores are broken by the unrounded values.
Layout, Motion, and Dual VQA by task
Layout and Motion are the two parts of Latent Similarity. The task columns split Dual VQA by question type. Relative direction combines the easy, medium, and hard subsets.
| Latent Similarity parts | Dual VQA by task | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Model and reasoning effort | Layout | Motion | Object count |
Absolute distance |
Object size |
Room size |
Relative distance |
Relative direction |
Route planning |
Appearance order |
| GPT-6 Astra xhigh | 87.6 | 90.2 | 51.0 | 52.6 | 76.5 | 46.2 | 48.1 | 77.5 | 75.8 | 60.1 |
| GPT-6.1 Sol xhigh | 88.4 | 91.0 | 52.0 | 45.1 | 72.9 | 45.4 | 51.9 | 73.8 | 72.7 | 56.8 |
| GPT-6.1 Terra xhigh | 86.9 | 89.5 | 45.5 | 46.8 | 74.1 | 51.5 | 52.7 | 72.6 | 81.8 | 60.6 |
| GPT-6 Astra high | 87.3 | 90.0 | 48.5 | 33.5 | 73.7 | 33.1 | 50.2 | 74.8 | 75.8 | 57.7 |
| GPT-6 Sol xhigh | 84.2 | 87.0 | 46.0 | 48.0 | 73.1 | 59.2 | 48.1 | 72.6 | 74.2 | 55.4 |
| Gemini 4 Argon high | 83.9 | 86.5 | 43.5 | 46.2 | 70.5 | 38.5 | 53.6 | 74.6 | 74.2 | 59.2 |
| Claude Opus 5.5 xhigh | 83.2 | 85.7 | 40.5 | 45.1 | 73.7 | 46.9 | 51.0 | 72.9 | 75.8 | 56.3 |
| Claude Sonnet 5.5 xhigh | 82.6 | 85.3 | 45.0 | 48.6 | 70.3 | 44.6 | 48.1 | 76.5 | 80.3 | 55.9 |
| GPT-5.6 Sol xhigh | 84.0 | 86.7 | 38.0 | 39.9 | 69.0 | 53.1 | 48.5 | 71.9 | 80.3 | 56.8 |
| Grok-4.6 xhigh | 82.9 | 85.5 | 40.5 | 42.2 | 66.2 | 46.9 | 46.4 | 73.6 | 78.8 | 56.3 |
| GPT-6 Luna xhigh | 81.6 | 84.7 | 32.0 | 44.5 | 68.4 | 41.5 | 44.4 | 74.8 | 78.8 | 59.2 |
| Grok-4.7 xhigh | 81.0 | 83.8 | 42.5 | 47.4 | 69.5 | 42.3 | 47.7 | 69.9 | 75.8 | 52.1 |
| DeepSeek V4.1 Flash 1017 max open-weight | 80.8 | 84.0 | 34.5 | 40.5 | 70.9 | 53.8 | 46.9 | 69.9 | 78.8 | 54.0 |
| Claude Opus 5 high | 79.8 | 82.9 | 42.0 | 46.2 | 66.4 | 43.8 | 46.0 | 71.6 | 78.8 | 56.8 |
| Qwen3.8-Max high | 79.9 | 82.8 | 42.5 | 37.6 | 65.8 | 45.4 | 45.6 | 72.4 | 74.2 | 62.4 |
| GPT-5.6 Sol high | 82.5 | 85.3 | 34.5 | 37.6 | 65.0 | 40.8 | 46.9 | 71.9 | 81.8 | 48.8 |
| Glimpse max | 79.2 | 82.2 | 37.0 | 45.7 | 66.7 | 42.3 | 43.5 | 71.6 | 77.3 | 59.2 |
| GPT-5.6 Terra high | 81.0 | 83.9 | 37.5 | 34.1 | 66.2 | 45.4 | 38.9 | 73.3 | 74.2 | 55.4 |
| GPT-5.5 high | 80.4 | 83.2 | 34.5 | 34.7 | 65.8 | 46.2 | 45.2 | 74.3 | 71.2 | 51.6 |
| Claude Haiku 5.5 xhigh | 78.6 | 81.7 | 33.5 | 45.7 | 67.7 | 38.5 | 47.7 | 70.4 | 77.3 | 56.3 |
| GPT-5.6 Terra xhigh | 81.6 | 84.3 | 33.0 | 30.6 | 65.8 | 43.1 | 41.4 | 70.9 | 77.3 | 55.4 |
| Claude Opus 5.5 high | 77.1 | 79.8 | 35.0 | 45.1 | 68.6 | 44.6 | 46.0 | 74.3 | 74.2 | 54.0 |
| GPT-5.6 Sol none | 79.1 | 82.0 | 31.0 | 37.0 | 67.1 | 37.7 | 49.4 | 75.6 | 72.7 | 48.8 |
| GLM-5.3-Flash xhigh open-weight | 77.0 | 80.3 | 35.0 | 38.2 | 64.5 | 46.2 | 45.6 | 76.3 | 71.2 | 61.0 |
| GPT-5.6 Sol medium | 80.1 | 83.1 | 35.0 | 40.5 | 64.3 | 33.8 | 38.9 | 73.3 | 74.2 | 56.3 |
| Muse Wonder xhigh | 76.3 | 79.5 | 32.5 | 46.2 | 67.9 | 46.9 | 46.0 | 70.7 | 75.8 | 54.5 |
| Muse Spark 1.3 xhigh | 78.3 | 81.2 | 35.0 | 36.4 | 64.1 | 35.4 | 45.6 | 70.2 | 72.7 | 59.6 |
| DeepSeek V4.1 Flash max open-weight | 74.8 | 78.1 | 29.0 | 51.4 | 67.9 | 43.8 | 45.2 | 73.3 | 69.7 | 54.5 |
| GPT-5.5 medium | 79.1 | 81.9 | 25.5 | 35.8 | 63.9 | 41.5 | 42.7 | 68.7 | 81.8 | 55.9 |
| GPT-5.6 Luna high | 79.6 | 82.7 | 28.5 | 36.4 | 65.2 | 34.6 | 36.8 | 72.1 | 74.2 | 51.2 |
| Grok-4.5 high | 77.6 | 80.4 | 35.0 | 39.3 | 64.1 | 42.3 | 44.8 | 68.2 | 75.8 | 50.2 |
| GPT-5.6 Sol low | 77.8 | 80.8 | 28.5 | 41.0 | 63.0 | 35.4 | 43.5 | 70.2 | 78.8 | 54.5 |
| GPT-5.6 Terra medium | 77.0 | 80.1 | 36.0 | 34.1 | 62.4 | 39.2 | 47.7 | 70.7 | 69.7 | 54.9 |
| Gemini 3.8 Flash high | 76.0 | 78.8 | 41.5 | 35.8 | 65.4 | 37.7 | 45.2 | 68.7 | 68.2 | 51.6 |
| GPT-5.5 low | 76.0 | 79.0 | 35.0 | 33.5 | 61.8 | 42.3 | 42.3 | 71.6 | 77.3 | 54.9 |
| GPT-5.6 Luna medium | 77.2 | 80.5 | 23.0 | 31.8 | 62.2 | 35.4 | 42.7 | 74.1 | 72.7 | 56.3 |
| Claude Sonnet 4.6 none | 73.8 | 76.9 | 30.5 | 37.0 | 63.9 | 43.8 | 44.4 | 74.1 | 68.2 | 57.3 |
| GPT-5.2 high | 74.4 | 77.2 | 39.0 | 38.2 | 60.9 | 46.2 | 37.7 | 72.6 | 72.7 | 57.7 |
| GPT-5.6 Terra low | 75.2 | 78.4 | 27.0 | 36.4 | 62.4 | 38.5 | 42.7 | 70.9 | 75.8 | 51.6 |
| Claude Sonnet 5 none | 72.9 | 76.3 | 30.0 | 39.9 | 62.4 | 36.2 | 46.4 | 71.9 | 77.3 | 57.7 |
| Gemini 3.1 Pro high | 72.9 | 76.1 | 30.0 | 44.5 | 65.2 | 43.1 | 40.2 | 69.7 | 75.8 | 54.9 |
| Claude Sonnet 5 high | 72.7 | 76.1 | 29.0 | 37.0 | 65.4 | 28.5 | 40.6 | 73.1 | 74.2 | 56.8 |
| Claude Opus 4.6 none | 73.0 | 75.9 | 28.0 | 39.3 | 63.7 | 30.0 | 45.2 | 71.9 | 78.8 | 53.1 |
| Claude Sonnet 4.6 high | 73.4 | 76.5 | 35.5 | 32.4 | 62.8 | 34.6 | 39.7 | 73.6 | 72.7 | 51.6 |
| Claude Opus 4.7 none | 70.9 | 74.3 | 36.0 | 41.0 | 61.5 | 34.6 | 43.1 | 72.4 | 75.8 | 54.9 |
| Muse Spark 1.2 xhigh | 74.1 | 76.7 | 33.5 | 32.4 | 62.8 | 36.9 | 40.6 | 65.5 | 71.2 | 52.6 |
| GPT-5.6 Luna low | 73.9 | 77.3 | 20.5 | 35.8 | 60.5 | 34.6 | 43.1 | 68.0 | 75.8 | 55.9 |
| Claude Opus 4.8 none | 70.4 | 74.1 | 30.5 | 37.0 | 62.0 | 35.4 | 44.8 | 70.4 | 74.2 | 49.8 |
| Claude Opus 4.8 high | 69.9 | 73.9 | 29.0 | 33.5 | 60.9 | 30.0 | 43.1 | 68.7 | 75.8 | 61.5 |
| Gemini 3 Flash high | 67.3 | 70.7 | 31.5 | 38.7 | 66.4 | 40.8 | 38.5 | 73.8 | 77.3 | 52.1 |
| Claude Opus 4.7 high | 69.3 | 72.9 | 33.5 | 42.2 | 61.5 | 35.4 | 39.7 | 68.2 | 69.7 | 56.3 |
| GPT-5.2 none | 68.7 | 72.2 | 30.0 | 41.0 | 60.9 | 31.5 | 40.6 | 71.9 | 69.7 | 58.2 |
| GPT-5.4 none | 66.3 | 69.6 | 23.5 | 41.6 | 64.8 | 43.1 | 37.2 | 68.9 | 62.1 | 55.4 |
| GPT-5.5 none | 71.8 | 75.4 | 21.5 | 24.3 | 59.8 | 30.8 | 37.7 | 67.5 | 69.7 | 44.6 |
| GPT-5.4 Mini none | 65.7 | 69.4 | 19.5 | 45.1 | 60.9 | 23.8 | 49.4 | 69.9 | 77.3 | 54.9 |
| Kimi-K2.5 none open-weight | 67.7 | 70.8 | 24.0 | 32.9 | 59.2 | 33.8 | 41.4 | 66.7 | 62.1 | 55.9 |
| GLM-5V-Turbo none | 65.4 | 68.7 | 25.5 | 42.2 | 61.5 | 36.9 | 37.7 | 67.5 | 77.3 | 44.1 |
| MiniMax-M3 none open-weight | 64.3 | 67.6 | 20.0 | 35.8 | 61.5 | 30.8 | 41.4 | 67.5 | 74.2 | 49.8 |
| Qwen3.5-122B none open-weight | 62.0 | 65.6 | 16.5 | 32.9 | 63.9 | 25.4 | 33.5 | 72.6 | 68.2 | 47.9 |
| Grok-4.3 high | 62.8 | 65.9 | 22.0 | 36.4 | 57.5 | 32.3 | 37.7 | 69.9 | 62.1 | 45.1 |
| Qwen3.5-397B none open-weight | 61.9 | 65.2 | 16.0 | 32.9 | 60.9 | 29.2 | 43.5 | 66.7 | 65.2 | 47.4 |
| Seed-2.0-Mini none | 59.8 | 64.0 | 17.0 | 31.8 | 61.5 | 20.8 | 38.5 | 73.1 | 72.7 | 47.9 |
| Qwen3.6-Plus none | 60.8 | 63.7 | 20.5 | 31.8 | 54.1 | 30.0 | 34.7 | 60.4 | 68.2 | 51.2 |
| Grok-4.3 none | 55.4 | 59.0 | 13.0 | 29.5 | 59.0 | 30.0 | 36.8 | 68.0 | 63.6 | 46.5 |
| Nemotron 3.5 Super VL max open-weight | 55.7 | 59.0 | 22.5 | 34.7 | 56.8 | 25.4 | 40.6 | 62.3 | 54.5 | 45.1 |
| Seed-2.0-Lite none | 56.2 | 60.6 | 10.5 | 33.5 | 57.9 | 30.0 | 34.3 | 65.3 | 60.6 | 39.0 |
| Qwen3.5-27B none open-weight | 55.8 | 58.9 | 13.5 | 27.2 | 54.5 | 26.2 | 35.6 | 61.9 | 69.7 | 43.2 |
Benchmark
BVB uses the 288 real indoor videos and 5,130 spatiotemporal questions of VSI-Bench, drawn from ARKitScenes, ScanNet, and ScanNet++. The agent sees only video frames. It gets no depth maps, segmentation, or 3D ground truth.
Every agent runs through the same harness,
Mini-BVB, with the same system prompt.
The harness has two tools. frames returns video
frames by timestamp or uniform count, and bash runs
commands, including Python for Blender, in a fresh Docker sandbox.
The agent decides how much of the video to view and how long to
work, and the only limit is a cost limit of $3 per scene. External asset
libraries are disallowed, so geometry is built from primitives and
basic Blender operations. The saved scene is rendered from its
animated camera and scored without re-entering the agent loop.
- Videos
- 288 from ARKitScenes, ScanNet, and ScanNet++
- Questions
- 5,130 in 8 task types
- Agent input
- Video frames only
- Tools
framesandbash- Sandbox
- Docker with Python, Blender 4.2, and FFmpeg
- Cost limit
- $3 per scene
- Output
result.blend, rendered with EEVEE
Results
Latent Similarity is higher than Dual VQA for every configuration on the leaderboard, by 9.4 to 28.0 points. The highest Dual VQA is 64.7, so every configuration loses at least 35.3% of the source-correct answers in its reconstructions.
Score and cost
The horizontal axis is the mean agent cost per scene on a log scale. Select a point, or use the arrow keys, to see its scores. A thin line then joins the reasoning effort settings of the same model.
Full results and analysis are in the paper.
Citation
@misc{tang2026bvb,
  title = {BVB: Benchmarking Agentic Video Understanding via Programmatic Reconstruction in Blender},
  author = {Yolo Y. Tang and Daiki Shimada and Jiayue Meng and Jing Bi and Pinxin Liu and Yicheng Wang and Yunzhong Xiao and Zhangyun Tan and Zeliang Zhang and Chao Huang and Susan Liang and Qianxiang Shen and Luchuan Song and Ali Vosoughi and Mingqian Feng and Melika Filvantorkaman and Chenliang Xu},
  year = {2026},
  eprint = {2609.15478},
  archivePrefix = {arXiv},
  primaryClass = {cs.CV},
  url = {https://arxiv.org/abs/2609.15478}
}